Can one representation serve different kinds of fMRI research?
An fMRI scan contains signals at thousands of locations. A common shortcut is to average them within predefined regions of interest (ROIs). This makes the input smaller, but fixes the spatial boundaries before the model learns anything. Two nearby voxels with different responses can become one regional average, and changing the atlas changes what the model receives.
Omni-fMRI starts from a different goal: learn voxel-level features once, then adapt them to demographic prediction, disease-related classification and task decoding. A shared encoder could reduce the need to build a separate representation for every dataset or atlas. The obstacle is scale: processing every spatial location with equally small patches produces a long, expensive token sequence.
Keep voxel information, adapt the amount of computation
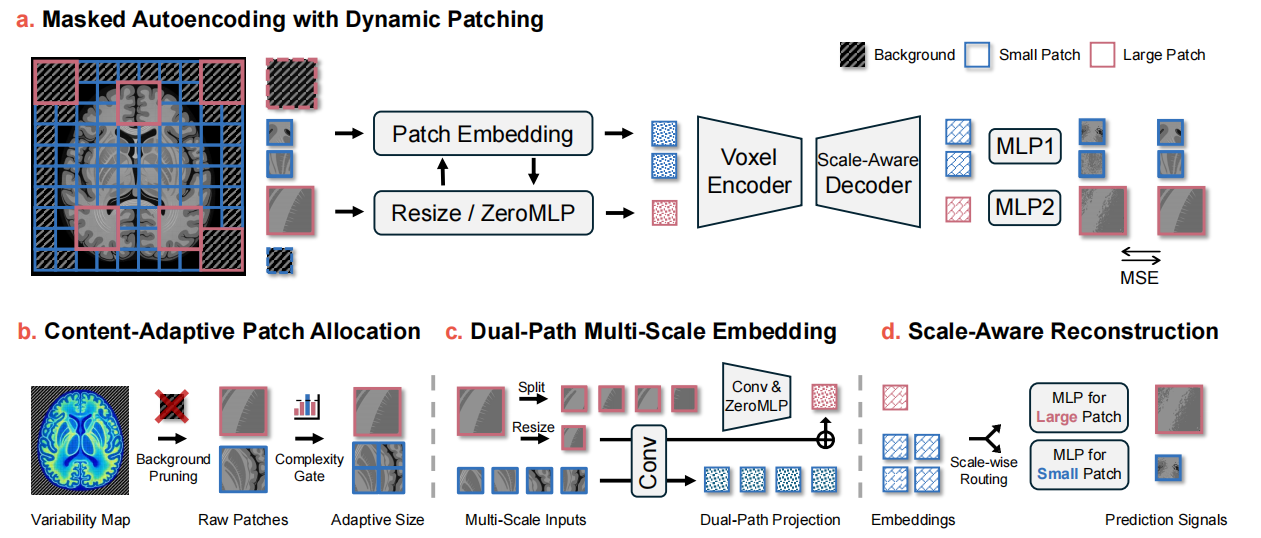
The input is a four-dimensional fMRI volume, not a list of ROI averages. The framework figure above follows three steps: choose patch sizes, embed the mixed-scale patches and learn to reconstruct masked signals. The encoder's features can then be paired with a downstream prediction head.
Use fine patches where signals vary
Dynamic patching removes non-brain background and measures local spatiotemporal intensity variance. Low-variance regions stay in larger patches; higher-variance regions are subdivided. This spends tokens on spatial detail without treating every part of the scan as equally complex. The selection criterion is signal variability, rather than a predefined anatomical atlas.
Bring different patch sizes into one encoder
A dual-path embedding combines a downsampled view of a large patch with features from its smaller sub-patches. Fine and coarse tokens enter the same latent space and ViT encoder. This gives the model a common feature interface while retaining information about location and scale.
Balance reconstruction across scales
Masked autoencoding trains the encoder to infer hidden fMRI signals from visible context. Scale-specific prediction heads reconstruct patches at their own sizes, and the loss accounts for patch volume and token frequency. Otherwise, larger patches could dominate learning simply because they contain more voxels.
Test reuse on new datasets, then freeze the encoder
Pretraining uses 49,497 sessions from nine datasets. The 11-dataset evaluation has two distinct parts: four datasets provide separate internal evaluation splits, while seven datasets are excluded from pretraining. Those seven are ADNI, SALD, BHRC, NKI, NSD, HCP task and StudyForrest. The latter group tests transfer to a different data source or experimental setting.
A shared starting point for different tasks
The pretrained encoder is adapted for age regression, disease-related prediction, visual image retrieval and brain-state or emotion prediction. These tests ask whether its features remain useful when both the target and the dataset change. They are downstream adaptation experiments, rather than zero-shot predictions from an untouched model.
Useful features before end-to-end adaptation
Linear probing keeps the encoder frozen and trains a lightweight prediction head. On ADNI AD classification, Omni-fMRI reaches 84.26% accuracy, compared with 71.64% for NeuroSTORM's frozen encoder. This more directly tests the information already present in the learned representation. Fine-tuning results are stronger overall, although the model does not lead every individual metric.
| Dataset / task | Evaluation | Omni-fMRI | Comparison |
|---|---|---|---|
| ADNI · AD classification | Fine-tuning · ACC ↑ | 88.77 ± 0.71% | NeuroSTORM · 84.26 ± 0.80% |
| ADNI · AD classification | Frozen encoder · ACC ↑ | 84.26 ± 0.87% | NeuroSTORM · 71.64 ± 0.66% |
| NSD · 100-way image retrieval | Fine-tuning · Top-10 ↑ | 23.08 ± 1.93% | NeuroSTORM · 20.83 ± 1.65% |
A common feature interface without fixing ROI boundaries
The main idea is to share the representation while leaving the downstream target flexible. Dynamic patching makes this voxel-level approach practical, and held-out datasets plus linear probing test two different aspects of reuse. Atlas-free refers to avoiding a predefined ROI parcellation; the study still standardizes spatial and temporal sampling before training.
From the project page to your own features
The official project page brings together the method, benchmark tables and a runnable quick start. The repository accepts prepared NPZ inputs shaped 96 × 96 × 96 × 40 and exports a global cls_token, patch_tokens and patch_coords. Start with the synthetic smoke test or notebook, then prepare your own scans using the documented pipeline.
A Universal Atlas-Free fMRI Foundation Model
Research post by fMRI Atlas, based on the original study linked above.
Post updated:
Read the paper’s abstract
Self-supervised fMRI foundation models have shown promising transfer performance, yet most rely on predefined region-level parcellations that discard fine-grained voxel information and introduce atlas-dependent biases. We propose Omni-fMRI, an atlas-free foundation model that operates directly on voxel-level signals. To enable scalable pretraining on 49,497 fMRI sessions across nine datasets, Omni-fMRI introduces a dynamic patching mechanism that substantially reduces computational cost while preserving informative spatial structure. To support reproducibility and fair comparison, we establish a comprehensive benchmark suite spanning 11 datasets and a diverse set of resting-state and task-based fMRI tasks. Experimental results demonstrate that Omni-fMRI consistently outperforms existing foundation models, providing a scalable and reproducible framework for atlas-free brain representation learning.
BibTeX
@article{wang2026omnifmri,
  title={Omni-fMRI: A Universal Atlas-Free fMRI Foundation Model},
  author={Wang, Mo and Ye, Wenhao and Xia, Junfeng and Zhang, Junxiang and Pan, Xuanye and Xu, Minghao and Deng, Haotian and Wen, Hongkai and Liu, Quanying},
  journal={arXiv preprint arXiv:2601.23090},
  year={2026},
  url={https://arxiv.org/abs/2601.23090},
  doi={10.48550/arXiv.2601.23090}
}